Land, power, engineering, and operations unified under one team. From powered shell to fully managed GPU compute — matched to your deployment requirements.
What We Do
From site selection and power procurement through design, construction, commissioning and operations — Coresphere stays involved across the full infrastructure lifecycle rather than handing the project from one party to the next.
Site
Selection & origination
Power
Procurement & grid
Design
Engineering & permits
Build
Construction management
Commission
Testing & handover
Operate
24/7 operations
Power secured before commitments
Utility capacity is confirmed before any commercial programme begins. Land and power are locked, not assumed.
Built to deployment specification
Every campus is engineered to tenant requirements — from substation architecture and cooling topology to fiber routing and resilience design.
Same team, full lifecycle
The people who originate the site and procure the power also manage construction, commissioning and operations.
We transform utility power into usable AI compute — end to end.
What We Engineer
The infrastructure behind the compute.
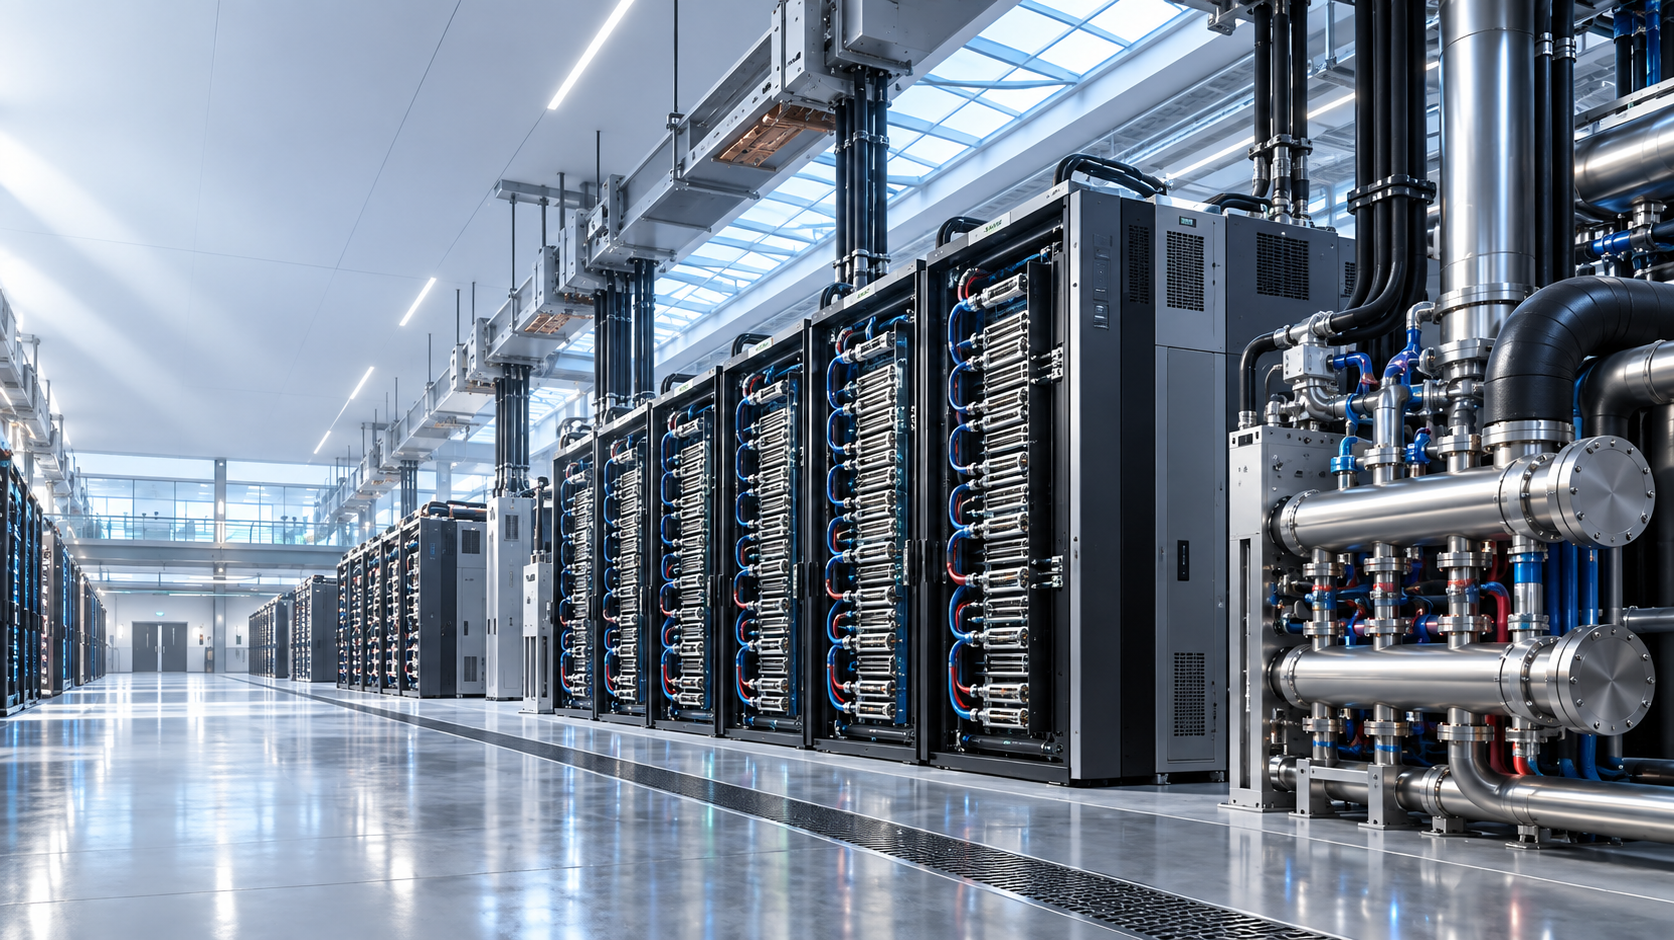
Securing megawatts is only the beginning. Coresphere engineers the power, cooling and connectivity required to turn utility capacity into deployable AI infrastructure.
From grid to rack.
Electrical architecture engineered for high-density, dynamic AI loads. Substation design, distribution topology and backup power systems are specified around the demands of large-scale GPU deployment — not designed for conventional colocation and then scaled up.
Designed for liquid from day one.
Closed-loop liquid-cooling infrastructure designed around high-density rack-scale compute. Liquid cooling is not a retrofit option added to air-cooled halls — it is designed into the facility architecture from the first drawing, with the structural, hydraulic and plant systems specified accordingly.
Built for AI clusters.
Carrier-diverse, high-bandwidth connectivity designed around the demands of large-scale AI workloads. Fiber routing, interconnection and carrier diversity are planned from the first site layout — not treated as a fit-out item to be resolved after the building is complete.
Built beyond today's rack.
Infrastructure designed around an evolving envelope of rack power, cooling and compute density. Facility systems are specified to accommodate increasing density requirements without fundamental redesign — so that the building does not become the constraint.
Engagement Models
A full spectrum — from powered shell to fully managed compute. Increasing managed scope as you move right.
Lowest CapEx · Fastest Power
Power-ready, weather-tight building with utility, connectivity and cooling distribution. Tenant fits out the white space to their own specification.
Operated Space
Racks, power and cooling in a Coresphere hall, fully operated by our team. Tenant brings their own hardware and connects to our managed network.
Your Design · Our Delivery
A campus or hall engineered around your exact deployment. We own the land and power, you drive the specification — from rack density to cooling topology.
Compute · Fully Managed
Fully managed, dedicated NVIDIA GPU clusters with managed Slurm, Kubernetes, storage tiers, security and 24/7 operations. Pure AI — no infrastructure ops.
Technical Framework
Rack-scale architecture, not retrofitted colocation.
Infrastructure designed around the demands of next-generation rack-scale compute. Power and cooling systems sized for high-density deployments from the first drawing.
Closed-loop, direct-to-chip liquid-cooling capability designed into the facility architecture from the outset — not added as an upgrade to an air-cooled building.
Utility-to-rack electrical infrastructure engineered for large, dynamic AI loads. Substation architecture designed for peak density, not average draw.
Carrier-diverse, high-bandwidth connectivity architecture designed for large-scale AI clusters. Fiber routing and interconnection planned from the first site layout.
Energy and water performance treated as engineering metrics. PUE and WUE measured and continuously improved — not cited as marketing claims.
Infrastructure designed to accommodate evolving rack power and cooling requirements without requiring fundamental redesign of the facility.
Technology Stack
Every layer — from physical infrastructure to AI/ML tooling — is selected for performance, vendor support, and long-term roadmap alignment.
Partnership Model
 Coresphere
Tell us your requirements. We'll match the right engagement model to your timeline, density, and budget.